
ModLens
Convert pasted images into structured OCR, layout, entity, and relationship evidence so text-only DeepSeek or GLM models can work with screenshots and document images.
Project overview
Convert pasted images into structured OCR, layout, entity, and relationship evidence so text-only DeepSeek or GLM models can work with screenshots and document images.
Core capabilities
Extract OCR and layout information
Extract OCR and layout information. This capability is documented in the repository README and still requires verification against the target DSH version and profile.
Identify entities and relationships in images
Identify entities and relationships in images. This capability is documented in the repository README and still requires verification against the target DSH version and profile.
Add named vision routes for text-only models
Add named vision routes for text-only models. This capability is documented in the repository README and still requires verification against the target DSH version and profile.
Return traceable structured image evidence
Return traceable structured image evidence. This capability is documented in the repository README and still requires verification against the target DSH version and profile.
Installation and usage
Install in DeepSeek Harness, reload the target environment as documented, and verify it with a low-risk scenario.
Let an AI Agent install it
Send this prompt to Codex, Claude Code, or another AI agent that can work with your local environment.
Help me install ModLens from https://github.com/liustack/modlens. Read the README, license, and installation files first. Confirm the current DeepSeek Harness version, target profile, and required dependencies. Use the repository's current command `npx -y @deepseek-ai/dsh plugin --profile web add @liustack/modlens@3.22.1`. Explain the profile, paths, and permissions that will change before running it. Follow the repository verification steps and report commands, changed locations, and visible results. Ask before requesting credentials, enabling extra network access or build scripts, overwriting files, or expanding permissions.- DeepSeek Harness Web starts successfully
- A working text-model route
- Endpoint and credentials when using a remote vision engine
npx -y @deepseek-ai/dsh plugin --profile web add @liustack/modlens@3.22.1- 1Check the environment and target profile
DeepSeek Harness Web starts successfully; A working text-model route; Endpoint and credentials when using a remote vision engine. Record the current configuration and installed plugins before changing anything.
- 2Run the current repository command
Run the following command. `npx -y @deepseek-ai/dsh plugin --profile web add @liustack/modlens@3.22.1` Stop and ask before enabling build scripts, providing credentials, or overwriting files.
- 3Reload and verify
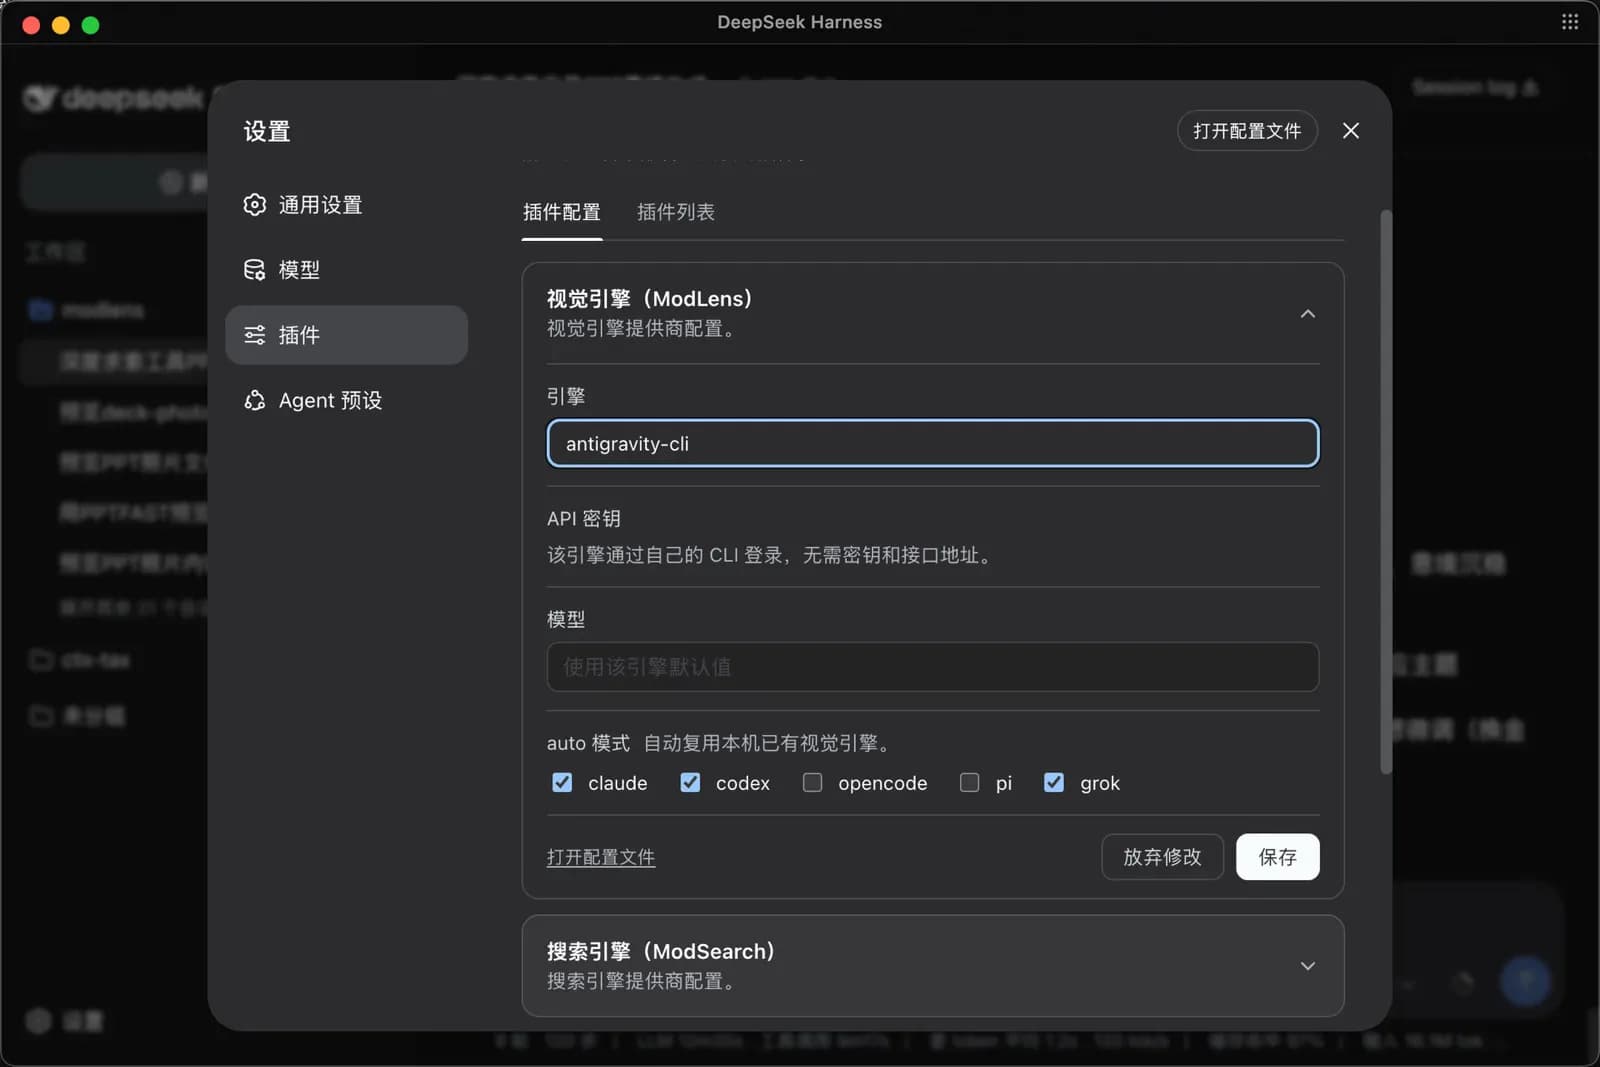
Confirm that a `(modlens vision)` route appears in the model selector, then paste a low-sensitivity screenshot and check for structured image evidence.
Confirm that a `(modlens vision)` route appears in the model selector, then paste a low-sensitivity screenshot and check for structured image evidence.
- Images may be sent to the configured external vision service
- Results still depend on the selected model and endpoint
- Sensitive material requires a privacy and quota review
Use cases
Analyze product screenshots and error dialogs
Start with a minimal ModLens scope in this scenario, then expand only after checking output, permissions, and compatibility.
Extract OCR and layout from document images
Start with a minimal ModLens scope in this scenario, then expand only after checking output, permissions, and compatibility.
Let text-only models compare multiple visual inputs
Start with a minimal ModLens scope in this scenario, then expand only after checking output, permissions, and compatibility.
Assessment
This assessment is based on the repository README, installation instructions, license, and maintenance metadata. Adds image input to text-only models; Returns OCR, layout, and relationship evidence; Provides a one-command pinned installation path. Images may be sent to the configured external vision service; Results still depend on the selected model and endpoint; Sensitive material requires a privacy and quota review. No local installation or long-term use is claimed.
Why it may be useful
- Adds image input to text-only models
- Returns OCR, layout, and relationship evidence
- Provides a one-command pinned installation path
What to know first
- Images may be sent to the configured external vision service
- Results still depend on the selected model and endpoint
- Sensitive material requires a privacy and quota review
README
ModLens
Overview
Convert pasted images into structured OCR, layout, entity, and relationship evidence so text-only DeepSeek or GLM models can work with screenshots and document images. Convert pasted images into structured OCR, layout, entity, and relationship evidence so text-only DeepSeek or GLM models can work with screenshots and document images.
Getting started
- Install in DeepSeek Harness, reload the target environment as documented, and verify it with a low-risk scenario.
- Convert pasted images into structured OCR, layout, entity, and relationship evidence so text-only DeepSeek or GLM models can work with screenshots and document images.
- The repository documents these main capabilities: Extract OCR and layout information, Identify entities and relationships in images, Add named vision routes for text-only models, Return traceable structured image evidence.
- Confirm that a `(modlens vision)` route appears in the model selector, then paste a low-sensitivity screenshot and check for structured image evidence.
Configuration
npx -y @deepseek-ai/dsh plugin --profile web add @liustack/modlens@3.22.1